What Is MQM Scoring? A Practical Guide for Localization Teams
MQM is the industry standard for scoring translation quality. Learn the error typology, severity levels, and how to apply it without drowning in spreadsheets.
August 30, 2026 · By Loqalit Team
MQM, Multidimensional Quality Metrics, is a framework for describing what is wrong with a translation, how badly it is wrong, and how much that matters. It replaces subjective verdicts like this reads awkwardly with a shared vocabulary that a linguist, a project manager, and an engineer can all act on.
If you have ever received LQA feedback that said only quality is poor, you already understand the problem MQM was built to solve.
The core idea: errors have a type and a severity
MQM separates two questions that teams usually collapse into one.
What kind of error is this? MQM organizes defects into a typology, a structured list of error categories. The most commonly used top-level dimensions are:
- Accuracy - the translation says something the source did not. Mistranslation, omission, addition, untranslated text.
- Fluency - the translation is wrong as a piece of language. Grammar, spelling, punctuation, register, inconsistency.
- Terminology - a term does not match the approved glossary or is used inconsistently across the product.
- Style - the text violates the brand voice or style guide even though it is grammatically correct.
- Locale conventions - dates, numbers, currency, addresses, or name order formatted for the wrong market.
- Design - the text breaks the interface: overflow, truncation, clipping, broken layout, overlapping elements.
How serious is it? Each error is assigned a severity, typically:
- Critical - causes real harm. A legally wrong disclaimer, an inverted price, a mistranslated safety warning, a broken checkout button.
- Major - meaningfully damages comprehension or trust, but the user can still complete the task.
- Minor - noticeable to a careful reader, low impact on the user.
- Neutral - flagged for the record, no penalty applied.
An error’s weight comes from combining these two axes. A minor fluency slip in a footer is not the same event as a critical accuracy error in a payment confirmation, and a scoring system that treats them identically will send your team chasing the wrong bugs.
How the score is calculated
The general shape of an MQM score is: start at 100, subtract penalty points for every error found, normalized against the size of the sample. A simplified version looks like this:
Score = 100 - (Total penalty points / Word count) x 100
Where each error contributes penalty points based on its severity weight, a common weighting is Critical 10, Major 5, Minor 1, though these values are configurable and should be tuned to your risk profile.
Two things matter more than the exact arithmetic:
- The weights encode your priorities. A fintech product should weight accuracy errors far more heavily than a marketing microsite. MQM is a framework, not a fixed rubric.
- The score is a summary, not the deliverable. A single number tells you whether to ship. The itemized error list tells you what to fix. Teams that report only the number lose all the actionable information.
Where MQM breaks down in practice
MQM is excellent at describing errors. It is silent on how you find them, and that is where most localization QA programs actually fail.
Automated methods can help find errors at scale; see how to evaluate translation quality automatically, from BLEU and COMET to LLM-as-a-judge with MQM.
The standard workflow is: export strings, send them to a reviewer, receive a spreadsheet of findings, map those findings back to the product. Every step of that loop introduces the same problem, the reviewer never sees the running product.
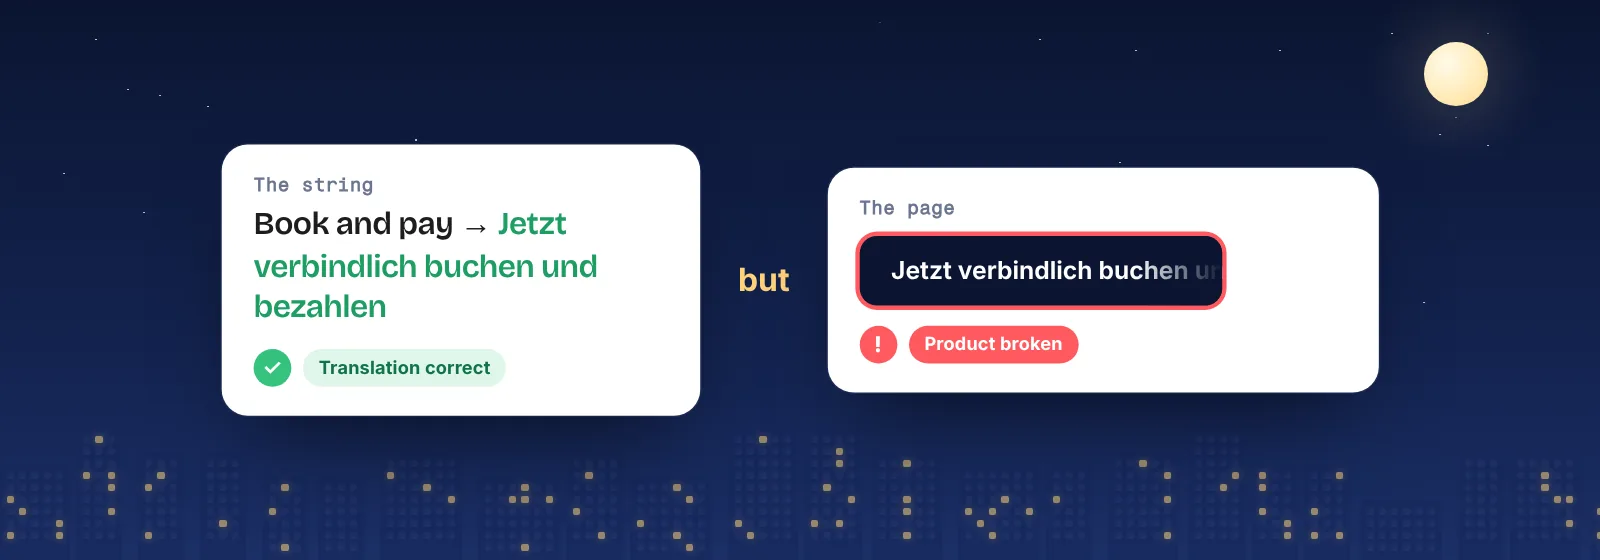
That matters because an entire MQM dimension is invisible in a spreadsheet. Design errors, overflow, truncation, clipped buttons, text that pushes a layout apart, do not exist at the string level. The string is fine. The rendered interface is broken. A reviewer working from a bilingual export will pass that string every single time.
The same blind spot affects accuracy. Open is a correct translation until you learn it labels a toggle rather than a verb. Free is correct until it appears next to a paid tier. Context-dependent errors are the most expensive kind to catch late, and they are exactly the kind a decontextualized review cannot see.
Tools that score translation quality with MQM
MQM is a framework, not a product, so tools implement it in different ways: some predict a score automatically, others help people annotate errors.
- Loqalit applies MQM categories and severity to findings on the rendered page (your live or staging site, in every language), with a screenshot for each, and posts accepted fixes to Crowdin or Phrase as comments. Best for: live websites and web apps.
- Lokalise AI scoring gives each string in the Lokalise editor a 0–100 score based on MQM. Best for: triaging strings inside Lokalise.
- Phrase QPS (Quality Performance Score) predicts, on a 0–100 scale, what a translation would score in an MQM review, at segment and document level. Best for: routing content automatically inside the Phrase platform.
- Alconost MQM annotation tool is a free, web-based tool for reviewers to annotate errors with the MQM typology, with adjustable severity weights and automatic score calculation. Best for: human LQA scoring and client reports.
- MQM Scorecard is an open-source application, developed at Brigham Young University, for scoring bilingual files with MQM metrics. Best for: teams that want a free, self-hosted scorecard.
Automated scores (Lokalise, Phrase QPS) are fast but predict quality. Annotation tools (Alconost, MQM Scorecard) capture a reviewer’s judgment. Rendered-page scoring (Loqalit) adds the design dimension a text-only score can’t see.
Applying MQM without the spreadsheet loop
A workable MQM program needs three things the traditional workflow does not provide.
Errors captured in context. An error report should show where the defect appears in the product, not just which row of a file it came from. A reviewer looking at the rendered screen can evaluate register, terminology fit, and layout in a single pass.
Consistent severity assignment. Severity is the most subjective part of MQM, and inter-reviewer variance is the usual reason scores are not comparable across releases. Defining severity against concrete, product-specific examples, not adjectives, is what makes the number trustworthy over time.
Continuous rather than batch measurement. A score produced once per release tells you what shipped. A score produced continuously tells you what is drifting. Most localization debt accumulates between formal QA cycles, in the strings nobody re-checked.
Use the severities as a release rule: block a release on critical and major findings →
Getting started
If your team has no MQM program today, do not begin by building a complete typology. Begin with three questions on your next release:
- Which errors would actually stop us from shipping? Those are your Critical definitions.
- Which error types do we keep finding in production? Those get the heaviest weights.
- Which of those types can a spreadsheet review even detect? The answer is usually not the expensive ones, and that gap is the case for changing how you review, not just how you score.
Which tool category can actually catch it in the first place is a separate question. See the localization QA tools category map for where MQM scoring fits against rule-based checkers, AI linguistic QA, and in-context tools.
Loqalit scans your live product in the browser and scores every defect it finds against MQM, in context, with the exact screen it appears on. Try the Chrome extension
Schedule it. Forget it. Ship it.
Start with a free QA report. We scan your live site in up to 3 languages and email you the findings with screenshots, MQM severities and suggested fixes.